Why Temperature 0 Does Not Make LLM Inference Deterministic
Sampling determinism is not the same as computational determinism.
A common assumption in AI systems is:
If temperature is set to 0, the model becomes deterministic.
That sounds reasonable.
After all, temperature controls randomness during token sampling. If we remove sampling randomness, shouldn’t the same prompt always produce the exact same result?
Not necessarily.
Temperature 0 can remove one source of variability.
It does not make the entire inference computation deterministic.
Sampling is only one layer
When temperature is greater than 0, token generation can involve probabilistic sampling.
Lowering the temperature reduces that randomness.
At temperature 0, implementations usually choose the highest-probability token directly.
That can make generation appear deterministic.
But the token selection step is only the final part of a much larger numerical computation.
Before a token is selected, the model performs a huge number of operations:
- matrix multiplications
- reductions
- normalization
- attention calculations
- routing decisions
- activation functions
Most modern inference systems perform these operations using floating-point arithmetic.
And floating-point execution introduces its own reproducibility challenges.
Floating-point arithmetic is order-sensitive
Floating-point addition is not perfectly associative.
In other words:
(a + b) + c
is not always bit-identical to:
a + (b + c)
The mathematical result may be effectively the same.
The binary representation may not be.
That matters because modern AI inference relies heavily on parallel execution.
Operations may be split across:
- CPU threads
- GPU kernels
- tensor cores
- devices
- distributed workers
If the execution order changes, the low-order bits can change too.
Usually, the difference is extremely small.
But small differences can accumulate.
And when two output probabilities are very close, even a tiny numerical difference can change which token wins.
So even with temperature set to 0, two runs can diverge.
Hardware can change the execution path
The same model may run on:
- x86 CPUs
- ARM CPUs
- NVIDIA GPUs
- AMD GPUs
- Apple Silicon
- different accelerator generations
Each environment may use different kernels, instruction sets, reduction strategies, and optimization paths.
The result can be numerically equivalent without being bit-identical.
For many applications, that is completely acceptable.
But if the goal is exact reproducibility, “close enough” is not enough.
Distributed inference makes the problem more visible
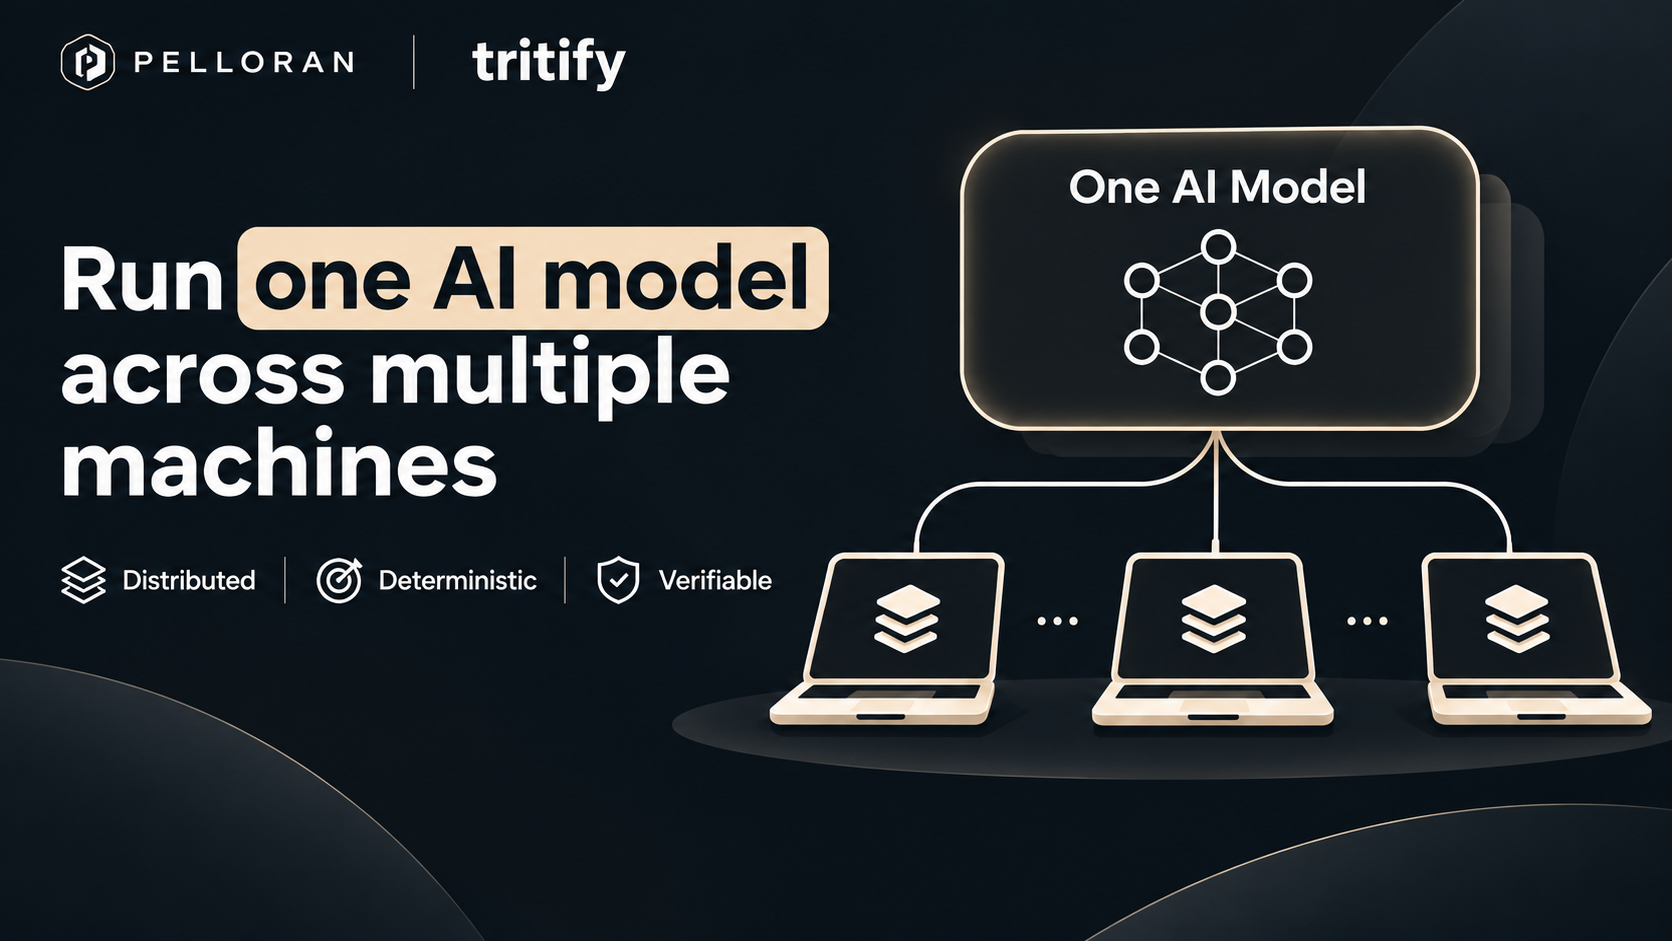
Now imagine one model running across multiple machines.
Different parts of the model may execute on different devices.
Intermediate activations are passed between machines.
The system still behaves as one model and one inference process.
But the number of possible execution paths grows.
At that point, reproducibility becomes a systems property rather than just a sampling setting.
The question is no longer:
Did we disable randomness?
It becomes:
Can the same computation be reproduced exactly across the whole execution path?
Determinism has to be designed into the computation
This is the problem we are exploring with tritify.
tritify uses deterministic integer execution for its reproducible inference path.
The goal is simple:
Same model.
Same input.
Same execution schedule.
Same bits.
This makes it possible to compare runs directly.
Not approximately.
Not with a tolerance threshold.
Exactly.
That matters for:
- regression testing
- debugging
- distributed inference
- reproducible research
- auditing
- verification
Temperature 0 is useful — but it solves a different problem
Temperature 0 can help reduce randomness at the token-selection layer.
It is useful.
But it should not be confused with deterministic inference.
There is an important distinction:
Temperature 0 removes sampling randomness.
Deterministic inference removes variability from the computation path itself.
Those are not the same guarantee.
Why this matters
As AI moves into more critical systems, reproducibility becomes more valuable.
If two runs differ, engineers need to know why.
Was it a model update?
A code regression?
A kernel change?
A different execution path?
Or simply numerical drift?
Exact reproducibility removes one source of ambiguity.
And once inference becomes distributed across multiple machines, that becomes even more important.
At Pelloran, this is one of the reasons we built tritify.
Open source:
https://github.com/pelloran-inc/tritify
Paper:
https://doi.org/10.5281/zenodo.23986737
Temperature 0 can make sampling deterministic.
It does not automatically make inference deterministic.
About the author
- Pelloran builds verifiable AI infrastructure for trustworthy intelligence. Our work spans AI memory, reasoning, provenance, and deterministic inference.
Comments
Join the discussionNo comments yet. Be the first to comment.
Deterministic AI Inference
A technical series from Pelloran on deterministic and reproducible AI inference, distributed execution, floating-point drift, verification, and the engineering ideas behind tritify.